A user deleted their account three weeks ago. Your app set deleted_at, hid the profile and moved on, which is what the soft-delete pattern is for. Then the e-mail arrives: they want their data erased. Not hidden, erased. Under the GDPR you have one month to answer (Article 12(3), extendable by two months for complex cases), and "we flagged the row" is not an answer.
Erasing one person turns out to be a question about your whole schema: which tables hold this user, in what order can they go, and which rows must stay because the tax office wants them for years. We built a lab schema, loaded the same 5.1 million rows into PostgreSQL 18.6, MySQL 8.4.11 and SQLite 3.54, and purged 2,000 soft-deleted accounts on each. Everything below was run and measured; the scripts are plain SQL plus a short Python loop.
The lab: 100,000 users, 2,400 soft-deleted
A small shop with a community attached. 2,400 users have deleted_at set; 2,000 of them are past a 30-day grace period (people do come back and ask for their account), so those are the ones to erase.
That spread is normal. The foreign keys were added by whoever wrote the first migrations; analytics, the audit log, the help desk import and the newsletter list came later, and nobody wired them to users with a constraint.
Why `DELETE FROM users` is the wrong first move
The one-liner, run on each engine against the 2,000 accounts past their grace period:
PostgreSQL and MySQL refuse, which is the good outcome. SQLite doesn't check foreign keys unless the connection has run PRAGMA foreign_keys = ON; it's off by default for backwards compatibility and has to be set on every connection. With it on, SQLite refuses too (FOREIGN KEY constraint failed). With it off, you get a database where the personal data is still there, now attached to nobody, which is harder to find later, not easier.
And even where the delete is refused, look at what would have happened if addresses had been on delete cascade like sessions: the orders would still block it, and the 2 million analytics events, the audit log, the tickets and the newsletter list would never have been touched, because no constraint connects them to users. A clean DELETE with no error proves nothing about erasure.
Step 1: find every column that holds the user
Two questions for the catalog. First, which columns have a foreign key to users, and what does each do on delete. Second, which columns look like they hold a user but have no constraint: names like user_id, actor_id, owner_id, and anything with email or phone in it. On PostgreSQL, one query does both and also says whether the column has an index (the first column of some index), which matters in step 3:
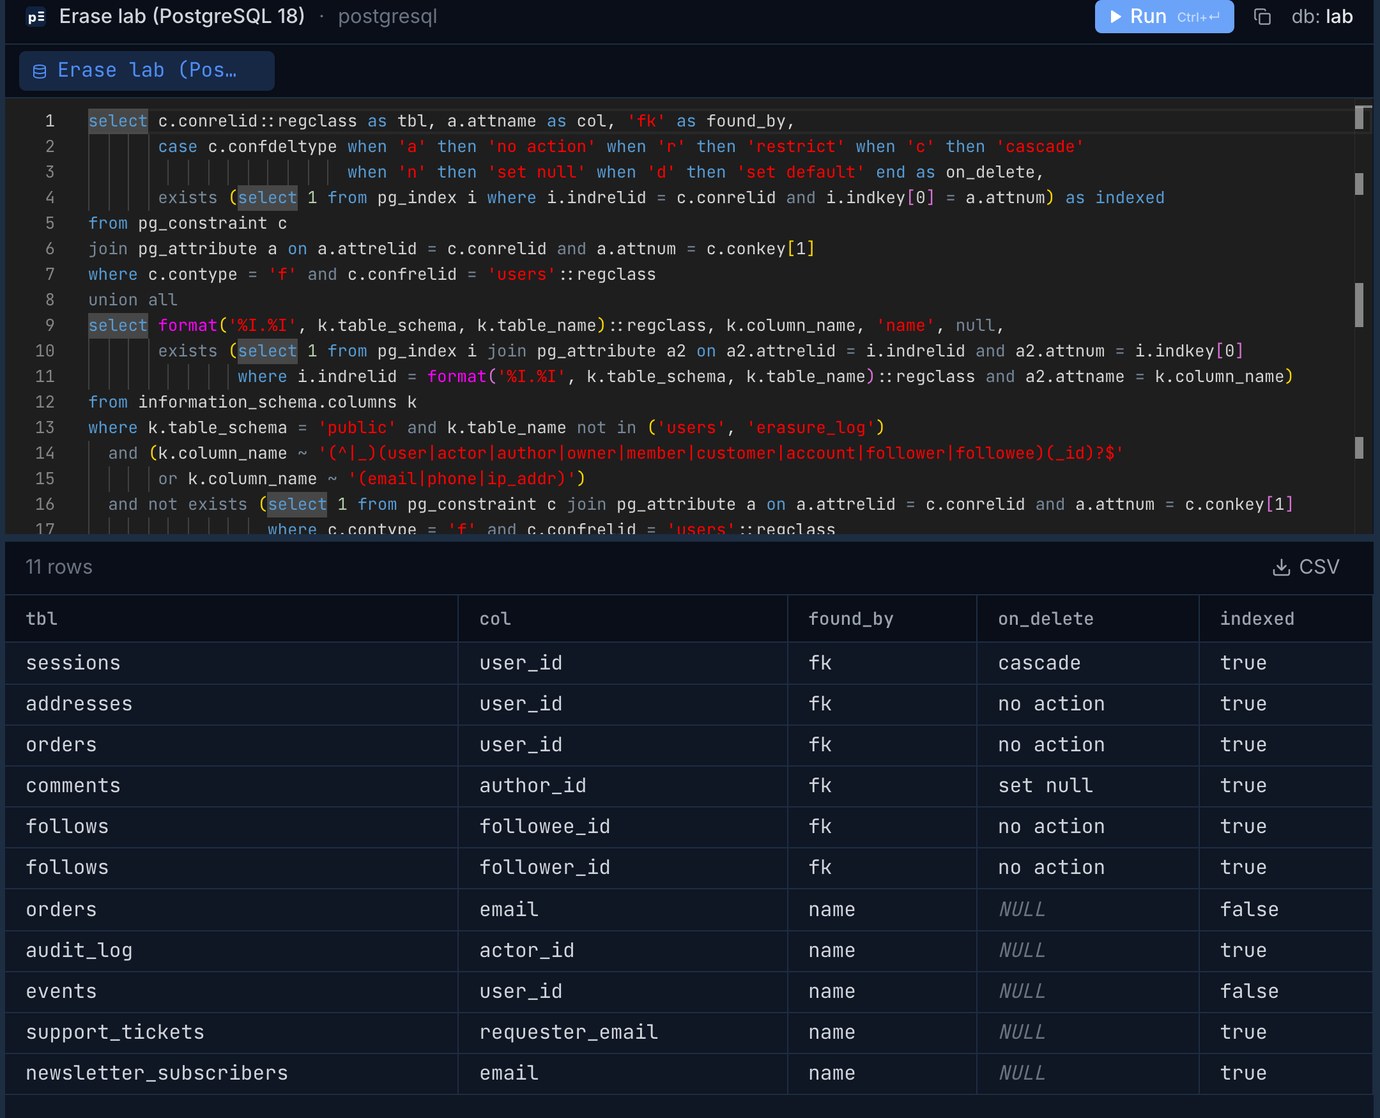
Eleven columns in nine tables. The name search found five the constraints didn't, including orders.email, a copy of the address taken at checkout that would have survived even a perfect cascade. It also found our own ledger table (erasure_log, below), which is why the query leaves it out. The name pattern is a net, not a proof: read the result, and grep the application code for tables it misses (a created_by or a recipient column would slip through this pattern).
The same two questions on MySQL 8.4, from information_schema (InnoDB creates an index on every foreign-key column itself, so the indexed check only matters for the name-found ones):
And SQLite, where the schema lives in sqlite_schema and the pragmas are table-valued functions. There's no regexp unless an extension adds it, so the name list is spelled out:
All three returned the same eleven columns on the lab. Keep this list in the repository next to the purge code and re-run the query in CI or before each purge run: the day someone adds a wishlists.user_id without telling you, the list grows by one and the purge should fail loudly rather than quietly skip it.
Step 2: decide per table: delete, keep, or anonymise
The catalog can't make this call. Write it down per table before any code, because it is what you'll show if anyone asks how you handle erasure requests:
Orders are the reason erasure isn't a cascade. Article 17(3)(b) of the GDPR lets you keep what a legal obligation requires you to keep, and tax law does: HMRC wants VAT records for up to 6 years, and Germany's AO § 147 asks for 8 years for accounting vouchers such as invoices since January 2025 (10 before). What it doesn't excuse is keeping the person attached to the record when the numbers would do. Which fields your accountant needs is their call, not the database's; an issued invoice PDF may have to stay exactly as issued. In the lab we kept the amounts, VAT, order date, country and postcode, and removed everything else that names or reaches the person.
Two side notes from the same table. comments was on delete set null: had we let the cascade handle it, 3,961 comments would have stayed, signed by nobody but still containing whatever the person wrote. And follows has two columns pointing at users; the purge needs both, or other people's follower lists keep a ghost.
Step 3: the purge, children first, in batches
Same order on all three engines, 500 users per transaction, IDs passed as a list. The orders update comes before the users delete so the foreign key never sees a dangling row; users goes last and only for rows still past the grace period, in case someone restored their account mid-run:
Collect the e-mail addresses first. Three of the tables only know the user by e-mail, and once the users row is gone you can't look it up any more. For 2,000 users:
Then the check that makes it an erasure and not a hope: count what's left in every column from step 1, by id and by e-mail. On all three engines every count came back 0: no session, address, order link, order e-mail, comment, follow, audit row, event, ticket or newsletter row for any of the 2,000.
The one table without an index decides the speed
events.user_id had no index because nothing ever looked up events by user. The purge does, once per batch, and each lookup is a full scan of 2 million rows. Time for the whole purge of 2,000 users, without and then with create index on events (user_id) (which took 0.49 s on PostgreSQL, 1.1 s on MySQL, 0.55 s on SQLite):
In a batch job that's seconds either way. The difference shows when erasure runs the way requests actually arrive: one person at a time, from a support tool or a nightly job. Deleting one user's events (about 20 rows), median of 20 users:
On MySQL the time is the smaller problem. InnoDB, at its default REPEATABLE READ, locks every index record a DELETE scans, not just the rows it deletes. We held the un-indexed delete for one user open and looked at performance_schema.data_locks, while a second session tried to update an unrelated event row:
Twenty-two rows deleted, the whole table locked against writers until commit. An erasure job doing that on a live analytics table stalls every event insert behind it. PostgreSQL's DELETE only locks the rows it actually deletes, so there it costs time, not blocking. Either way: any column the purge filters on gets an index, and the discovery query's indexed column tells you which ones are missing. For the same problem on foreign keys, where the slow part hides inside the constraint trigger, see Foreign keys without an index: slow deletes and lock waits.
What the column search can't see: free text
After the purge, every column from step 1 was clean. The data wasn't. 3% of the audit log is staff actions (email_changed by a support agent), and those rows have the agent in actor_id and the user only inside a text column: user 48211: ada.moss48211.old@example.com -> ada.moss48211@example.com. Deleting by actor_id never touches them.
Two lessons from those 621 rows. Searching free text for e-mails is slow (60 million LIKE comparisons) and incomplete: the old address in that same row, .old@, isn't in users any more, so a search by the current e-mail finds the row but a replace() of the current e-mail would leave the old one in place. Redact the whole value, don't patch out the parts you know about. And if a text column is going to mention users, give it a structure you can query (here, the id at a fixed place, or better a subject_user_id column) so the next erasure is a 36 ms lookup instead of a scan.
On the lab that rewrote the 621 rows to user 58579: [erased] in 70 ms; afterwards no staff row for an erased id contained an @.
Ticket bodies, comment texts that mention someone by name, JSON blobs, uploaded files and anything copied into a search index or a data warehouse are the same problem. The database can find the columns; it can't read your free text for you. List those places once, by hand, next to the step 2 table.
Backups: the ledger that survives a restore
Erased rows stay in last week's backup. The UK regulator's guidance, for one, doesn't expect you to rewrite backups; it expects the copy there to be "put beyond use" until the backup is overwritten on its normal cycle, and you should tell the person that. A restore is where it goes wrong: the erased rows come back as live data unless the erasure is applied again. That needs a record of who was erased that isn't itself personal data in any useful sense: the lab's erasure_log holds the user id and the time, nothing else, no e-mail and no name (keeping the e-mail "to prove we erased it" would defeat the point).
The comment is the important line. The ledger inside a restored backup is as old as the backup and doesn't know about later erasures; keep a copy outside the database (exported with each purge run, or in a separate small database), and make "re-run the purge from the ledger" a step in your restore runbook. If you use point-in-time recovery, the same applies: restoring to the second before a bad DELETE brings back every erasure after that second, too.
Checklist
If your accounts use deleted_at already, Soft deletes in SQL covers the queries that forget the filter and the unique keys that need it; the purge above is the step that finally removes those rows. And for bulk cleanup by date rather than by person, Deleting millions of rows without hurting production has the batch sizes measured.
Run the discovery query, read every table the user touches and check the counts after a purge in one grid, on PostgreSQL, MySQL, SQLite and more. Pilotbase is free for Windows, macOS and Linux, or Docker on a server.
Get PilotbasePurge slow on PostgreSQL? Paste the EXPLAIN ANALYZE of the DELETE into explainViewer: it lists the foreign-key triggers with their share of the time and names the child column that needs an index.
Open explainViewerSources: GDPR Article 17 (right to erasure; 17(3)(b) legal obligation) and Article 12(3) (one month, extendable by two); HMRC CH15100 (VAT records, retention period not exceeding 6 years); Stripe's summary of invoice retention in Germany (AO § 147, 8 years for accounting vouchers from 2025); PostgreSQL 18 documentation: pg_constraint (confdeltype), foreign keys (referencing columns are not indexed automatically); MySQL 8.4 Reference Manual: locks set by different SQL statements (a DELETE sets record locks on every index record it scans), KEY_COLUMN_USAGE, REFERENTIAL_CONSTRAINTS; SQLite foreign key support (off unless PRAGMA foreign_keys = ON, per connection); ICO guidance on the right to erasure (backups). Our test: PostgreSQL 18.6, MySQL 8.4.11 and SQLite 3.54 on an Apple-silicon Mac mini, November 2026; the same made-up 5.1 million rows on each (100,000 users, 2,000 erased), 500 users per transaction, times from a Python client on the same machine. This article describes database mechanics, not legal advice: retention periods depend on your country and business.